
When TypeSafe introduced Jev, it added a different intelligence primitive to the agent stack. Large language models generate open-ended text, code, commands, and plans. Jev receives state plus typed questions, then returns structured answers with probabilities. That narrower contract makes it useful wherever software needs a fast judgment from a closed set. Developers quickly explored command review, policy checks, model selection, browser actions, and workflow routing. We had already brought Jev into SuperQodethrough the SystemOne Harness, GEPA-guided decision tuning, and progressive tool discovery. Each integration used the same underlying idea: let a specialized decision model evaluate bounded choices while the surrounding harness owns control flow. Then Daniel Farina published an experiment called Nitro. He placed Jev in front of Grok Build and asked it to choose which tools the coding model should see for each turn. His measurements reported lower token use and lower cost on the tested tasks. The result exposed a broader opportunity. Every open coding harness carries a tool catalogue. Many send that entire catalogue on every model call. A general routing layer could serve far more than one CLI.
Jev as a Tool-Routing Primitive
Jev is TypeSafe AI’s first System One model. Its interface centers on three typed question forms. Choiceselects an item from a caller-defined set and returns a probability distribution. Score places an item on an ordered rubric. Noul evaluates a binary proposition with a probability between zero and one. Questions in one request are evaluated against the same state in parallel. Tool routing has the shape Jev expects. The harness already knows the task, the conversation state, and every available tool name and description. The decision stays bounded: will this turn need a given tool at any step, including validation? Jev supplies probabilities; policy code applies thresholds, dependency rules, and safety constraints. The division of responsibility matters. Jev selects definitions for the catalogue. It never creates a shell command, file path, patch, or tool argument. The coding model remains the author of each action. The harness continues to enforce permissions and decide whether execution may proceed.
From SystemOne to Cross-Harness Routing
Our first Jev work focused on decisions inside a native harness. The SystemOne Harness added typed tool gates, rubric evaluation, standalone decision packs, and shadow traces. It gave us a clear boundary between generation, judgment, and policy. Next came SystemOne Tune. GEPA uses execution evidence to improve reviewed question packs, compare candidate policies on a sealed split, and accept an update through an explicit gate. This work treats a decision policy as an artifact with versions, evidence, and evaluation history. Progressive tool discovery extended the concept into catalogue selection. SuperQode retrieves candidates, sends the bounded set to Jev, inspects the returned distribution, and activates the selected schema when confidence and separation checks pass. A permission check still runs before any execution. Retrieval narrows the search space; Jev verifies the candidate; policy determines activation.
Nitro approached the same pressure point from another direction. Daniel modified the Grok Build sampling loop, placed one Noul question per tool into a single Jev request, retained six workspace primitives, and held the result for the full turn. His article reports eight tools kept from a catalogue of twenty-five on coding tasks, with the first-step prompt moving from 17.8K tokens to 9.5K. In the representative comparisons highlighted in the article, he measured cost reductions between 22 and 40 percent. Two runs per cell make this an early experiment, and Daniel states that limitation in the article. The architecture remains compelling because it targets repeated schema context without changing the coding model.
The Context Cost of Tool Catalogues
A coding-agent request contains more than conversation history. Tool names, descriptions, parameter schemas, enums, examples, permission hints, and provider metadata may occupy thousands of tokens before the model sees the current task. Browser controls, image generation, workflow management, subagents, schedulers, remote resources, and diagnostic functions can all travel with a request that only needs repository search and a test command. That catalogue is sent again as the loop continues. Prompt caching can reduce the bill when the prefix stays stable, yet a large cached prefix still consumes context and carries a charge on providers that meter cached input. Cache behavior also varies by minimum prompt size, retention window, and elapsed generation time. A smaller stable catalogue improves the structure of every subsequent request. Removing tools too aggressively creates a different failure mode. A task may begin with code reading and later need a test runner, process inspection, or an edit. The route therefore covers the entire turn and asks about completion, including checks. Core workspace primitives stay present even when their probability falls below the configured threshold.
SuperQode Routing Architecture
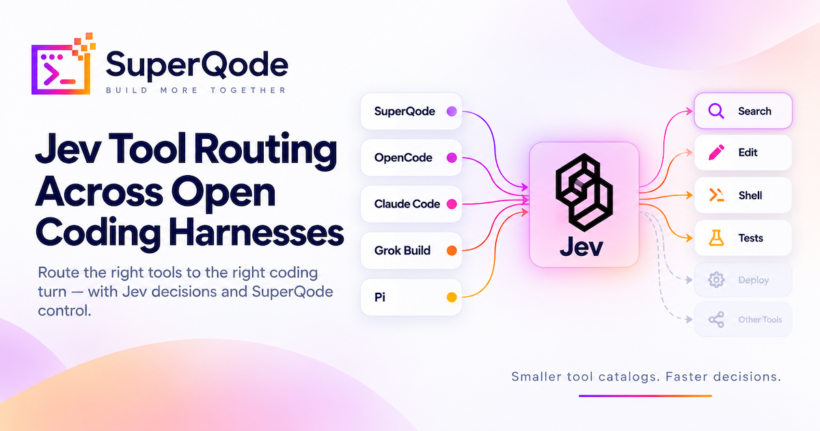
SuperQode 2.4.10 ships Jev Tool Routing as a reusable layer for open coding harnesses. It can run inside SuperQode, beside an existing CLI, in a Python process, through a local gateway, over HTTP, or through MCP. Every surface reaches the same routing core.
The routing sequence has six stages:
- Capture the catalogue. An adapter reads the tool definitions before the model request is constructed.
- Build one closed-set decision. The router sends the turn state and one Noul question for each tool in a single Jev call.
- Apply the safety floor. Repository reads, search, edits, shell access, and process dependencies can remain available through protected rules.
- Freeze the route. A stable
turn_idreuses the same selection for every model step in that turn. - Preserve the original objects. Selected definitions keep their provider-specific schema and metadata.
- Fall back to the full set. Timeouts, transport errors, incomplete answers, or an empty route leave the complete catalogue in place.
Shadow mode records the proposed reduction while forwarding every tool. Enforce mode forwards the selected set after teams have inspected traces and verified their workflows. The threshold defaults to 0.30, with protected tools and dependency rules taking precedence.
Local Evaluation and Controlled Adoption
Trust begins on the developer’s machine. The setup command detects installed harnesses, checks Jev connectivity, and prints the available routes. Verification uses a controlled catalogue to confirm schema reduction and same-turn cache reuse without calling a coding model.
uv tool install superqode==2.4.10
export TYPESAFE_API_KEY="your-typesafe-api-key"

superqode optimize setup
superqode optimize doctor
superqode optimize verify opencode
optimize run starts a loopback gateway, injects a process-scoped endpoint override, launches the chosen harness, prints aggregate routing metrics, and removes temporary state. Persistent vendor configuration stays untouched. Managed launchers such as opencode-jev offer a short command once the route has been reviewed.
# Observe recommendations while the full catalogue stays available
superqode optimize run opencode -- "review this repository"

# Create managed launchers after reviewing the evidence
superqode optimize enable opencode claude grok pi

# Start a routed session
opencode-jev run "review this repository"
Credentials remain separate. The local router reads TYPESAFE_API_KEY. A coding provider continues to use its own key or subscription. Generated OpenCode and Pi configuration receives a local placeholder where needed, while the gateway inserts the upstream credential at request time.
A Shared Core Across Integration Surfaces
Open harnesses expose different seams. Some accept an OpenAI-compatible base URL. Claude Code uses the Anthropic Messages protocol. OpenCode and Pi can speak native Gemini. A Python framework may prefer an in-process call. MCP clients need a tool-shaped interface. SuperQode covers those paths without creating a separate decision policy for each product.
- Native SuperQode: the router sits directly in the harness loop.
- Gateway adapters: OpenAI Responses, OpenAI Chat Completions, Anthropic Messages, and Gemini
generateContentrequests are supported. - Managed launch profiles: OpenCode, Claude Code, Grok Build, and Pi receive temporary endpoint configuration.
- Python SDK: a harness can call the routing core in-process and keep HTTP out of its local path.
- Service API:
POST /v1/route-toolsprovides a provider-neutral request contract. - MCP: local stdio and hosted Streamable HTTP expose
route_toolsto compatible clients.
The Python interface is deliberately small:
from superqode.jev_tools import JevToolRouting

router = JevToolRouting(mode="enforce")
result = await router.route(
    task="Review this repository and run its tests",
    tools=tool_catalogue,
    turn_id="turn-123",
)

model_tools = list(result.tools)
MCP offers a convenient shared capability, with one architectural boundary. An MCP server can route a catalogue supplied by its caller. It lacks access to hidden built-in tools inside another harness. Gateway and native adapters handle that interception point.
# Local HTTP and Streamable HTTP MCP service
export TYPESAFE_API_KEY="your-typesafe-api-key"
superqode serve jev

# Local stdio MCP surface
superqode optimize mcp
Watch Demo
Harness Coverage and Integration Boundaries
OpenCode, Claude Code, and Grok Build have routable gateway profiles. Pi follows the same path and gains more room for reduction when extensions expand its compact core catalogue. SuperQode uses the router directly. Codex reaches the gateway, although subscription traffic receives its built-in tool catalogue from the server. SuperQode reports this profile as gateway-limited and avoids catalogue-saving claims for that route. Antigravity is visible in the doctor command as detect-only until its CLI offers a model endpoint hook. These labels are part of the feature. A routing product needs precise capability reporting because a successful proxy connection says little about where tool schemas entered the request.
End-to-End Benchmark Across Three Harnesses
On 21 September 2026, we ran a compact end-to-end comparison with SuperQode 2.4.10. Every harness received the same calculator task: read two Python files, execute a two-test unittest suite, report its status, and evaluate add(19, 23). Shadow mode supplied the complete catalogue to the coding model. Enforce mode supplied Jev’s selection. Grok Build, Claude Code, and OpenCode each ran twice per mode in alternating order. Every included run returned the expected value and a passing test result. The structure follows Daniel’s early Nitro study: hold the task and model steady inside each harness, compare a full catalogue with a routed catalogue, retain provider-reported usage, and record elapsed time. Input figures combine uncached input, cache creation, and cache-read input across every model call. Cost comes directly from each harness report. Wall time includes gateway startup, the Jev decision, model calls, and tool execution.
| Harness and model | Coding tools | Schema reduction | Outcome |
|---|---|---|---|
| Grok Build 1.0.40, grok-4.6 | 25 to 7 | 75.8% | 4 of 4 passed |
| Claude Code 2.1.275, Haiku 4.5 | 28 to 2 | 86.0% | 4 of 4 passed |
| OpenCode 1.17.11, Gemini 3.8 Flash | 10 to 6 | 41.1% | 4 of 4 passed |
| Harness | Average input, shadow to enforce | Input change | Average cost, shadow to enforce | Wall time, shadow to enforce |
|---|---|---|---|---|
| Grok Build | 33,188 to 16,287 | 50.9% lower | $0.04261 to $0.02766 | 11.64s to 13.92s |
| Claude Code | 112,584 to 30,744 | 72.7% lower | $0.03582 to $0.01302 | 10.38s to 10.61s |
| OpenCode | 33,172 to 32,403 | 2.3% lower | $0.02728 to $0.02709 | 9.08s to 10.11s |
Grok produced the closest comparison with Nitro. Its two coding calls exposed twenty-five tools and Jev kept seven. The aggregate report also contained a one-tool utility request, yielding fifty-one to fifteen tool entries and 89,640 to 21,730 schema bytes per run. Average provider-reported cost fell 35.1 percent. Elapsed time increased in this small sample, which supports Daniel’s observation that the primary gain sits in input and cost. Claude exposed the largest catalogue. One shadow decision reached the 1.5-second timeout by two milliseconds, so the router failed open and Claude received all twenty-eight tools. The matching enforce decision completed in 1,458 milliseconds and kept two tools. The second pair completed routing in both modes. Across the two repetitions, average reported cost fell 63.7 percent and reported input fell 72.7 percent, with elapsed time separated by 0.23 seconds.
OpenCode delivered a stable schema result and a useful warning about end-to-end interpretation. Jev consistently selected six of ten tools and removed 41.1 percent of serialized schema bytes. One enforce repetition added an extra model step, leaving average input and cost effectively flat while elapsed time increased by about one second. Schema reduction creates an opportunity; model behavior still determines the final bill.
Isolated Routing Evaluation
A second evaluation isolates the router from coding-model variance. Five labeled scenarios share a twenty-tool catalogue. Each label identifies the tools required to complete the task, allowing the run to measure selection reduction and required-tool recall directly.
| Scenario | Tools | Reduction | Required recall | Latency |
|---|---|---|---|---|
| Workspace test | 20 to 6 | 70% | 100% | 810ms |
| Web research | 20 to 9 | 55% | 100% | 620ms |
| Image task | 20 to 7 | 65% | 100% | 682ms |
| Database analysis | 20 to 7 | 65% | 100% | 567ms |
| Browser form | 20 to 7 | 65% | 100% | 655ms |
| Average | 64% | 100% | 667ms |
The authenticated Cloud Run deployment selected the same tool sets across all five scenarios. Its average server-reported Jev latency was 556 milliseconds. This gives the local and hosted surfaces the same selection result while preserving deployment choice. Pi’s stock four-tool catalogue remained four tools in both modes, with passing tasks. Codex completed the calculator task through ChatGPT-authenticated traffic and reported 22,769 input tokens, while its request carried zero client-visible tool definitions. That route remains gateway-limited. Antigravity remains detect-only because its CLI lacks a model-endpoint hook. Two runs per cell remain a compact sample. The figures establish current integration behavior and reveal harness-specific variance. Longer tasks, extension-heavy catalogues, additional repositories, and more repetitions belong in the next evaluation round.
Hosted Deployment
Local operation remains the fastest way to evaluate the feature. Teams that want one shared decision service can use the authenticated deployment at jev.superqode.dev. It runs the same bounded in-memory turn cache and routing contract as the local service.
curl https://jev.superqode.dev/v1/route-tools -H "Authorization: Bearer " -H "Content-Type: application/json" -d @route-tools-request.jsonThe service accepts bearer authentication for remote binds. The request contains the task state, tool definitions, mode, threshold, and turn identifier. Responses include kept and dropped names, latency, cache status, and the selected tool objects. The service routes definitions only; upstream model calls remain with the harness.
Operational Value of a Shared Routing Layer
Maintaining a deep plugin for every coding CLI would tie the feature to many release cycles and extension systems. A shared core with thin launch profiles changes that maintenance equation. Protocol adapters handle wire formats. Harness-specific code stays limited to discovery, endpoint injection, and documented capability boundaries. This structure also gives open-source maintainers several adoption paths. They can import the Python SDK, call a local service, connect through MCP, or place the compatible gateway in front of an existing model endpoint. A direct native hook remains available when a project wants the smallest latency and full control over turn identity. The deeper benefit concerns harness ownership. Tool selection becomes an inspectable policy with thresholds, protected capabilities, traces, evaluation data, and versioned behavior. Teams gain a place to study which schemas are useful for their repositories instead of accepting a fixed catalogue assembled elsewhere.
Evaluation Roadmap
The next stage is evidence at wider scale. We plan to evaluate longer coding sessions, extension-heavy catalogues, multiple providers, cache boundaries, false removals, latency distribution, and total billed input. Shadow reports will be especially valuable because they can compare the proposed route with the tools a session eventually used. We also want better calibration by harness and repository type. A browser-oriented project, an infrastructure repository, and a Python library need different protected sets. SystemOne Tune gives us a path to improve those decisions from execution evidence while retaining a sealed comparison and an acceptance gate.
Jev Tool Routing is available today in SuperQode 2.4.10. Start locally, inspect shadow evidence, verify the adapter, and enable enforcement when the route fits your workflow. The source, Docker image definition, Cloud Run configuration, SDK, gateway, MCP server, tests, and command documentation live in the SuperQode repository.
Acknowledgements
Jev is created by TypeSafe AI. Daniel Farina’s Nitro experiment identified tool-catalogue routing as a practical cost lever inside Grok Build and published the measurements that prompted this broader implementation. SuperQode carries the idea across open harnesses through a local-first, provider-neutral routing layer.
Originally posted on Superagentic AI blog here